SanreMello Corpus: Seven Decades of Sanremo and Melodifestivalen in Data
CLIN 36, 2026 (poster)
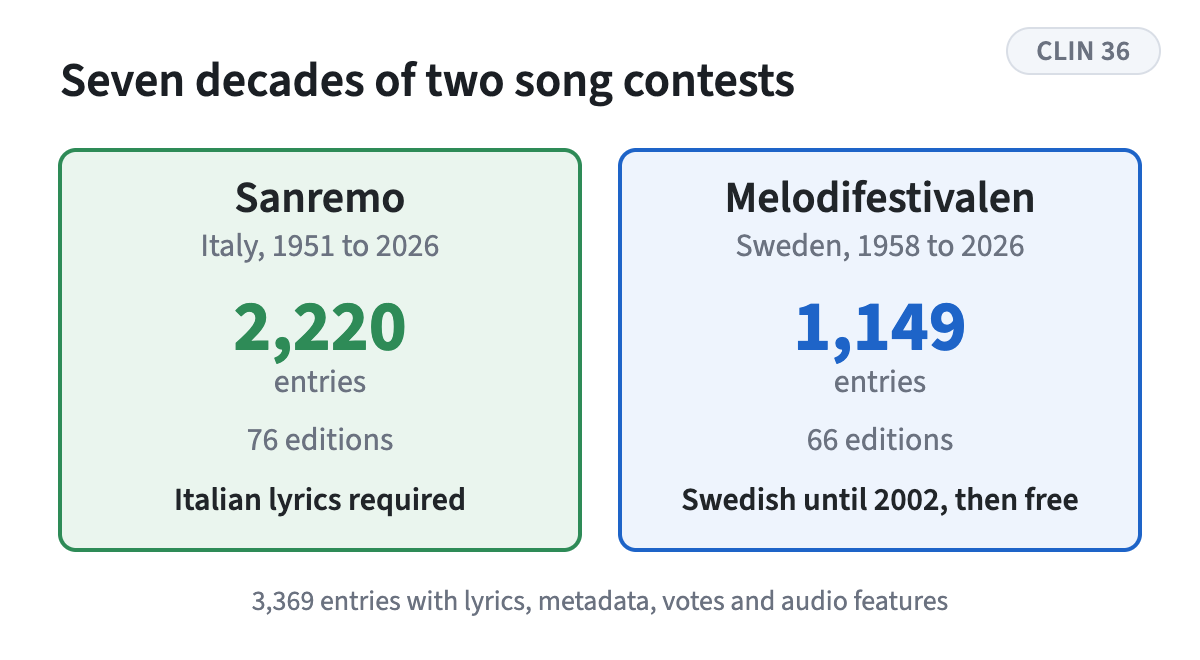
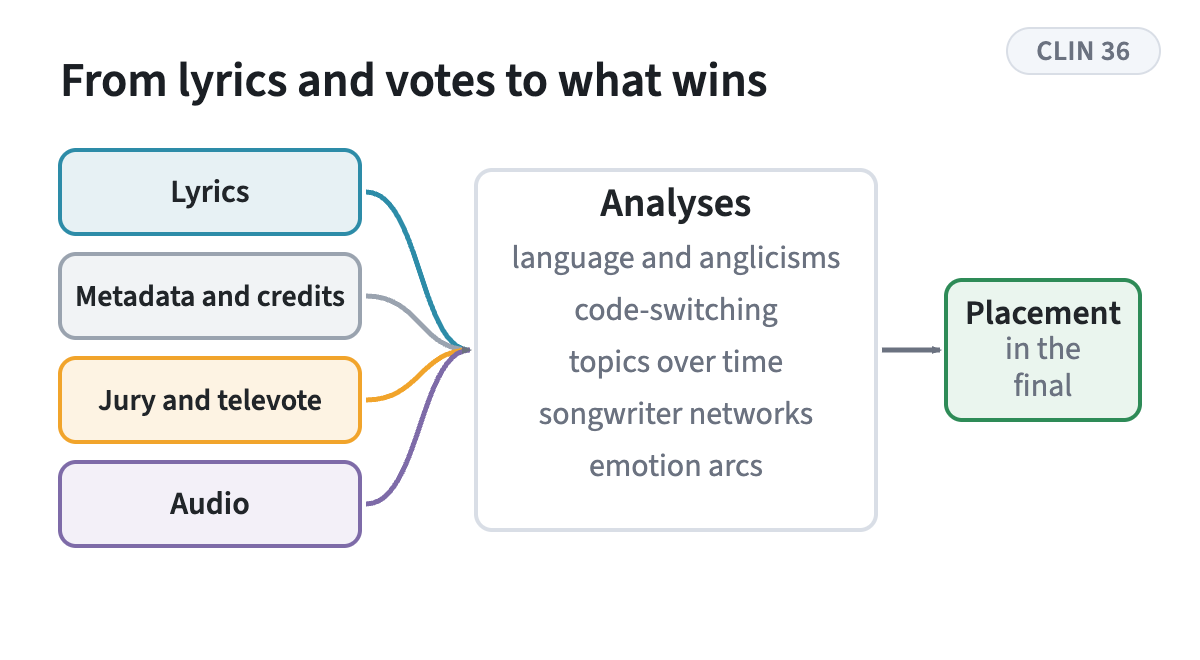
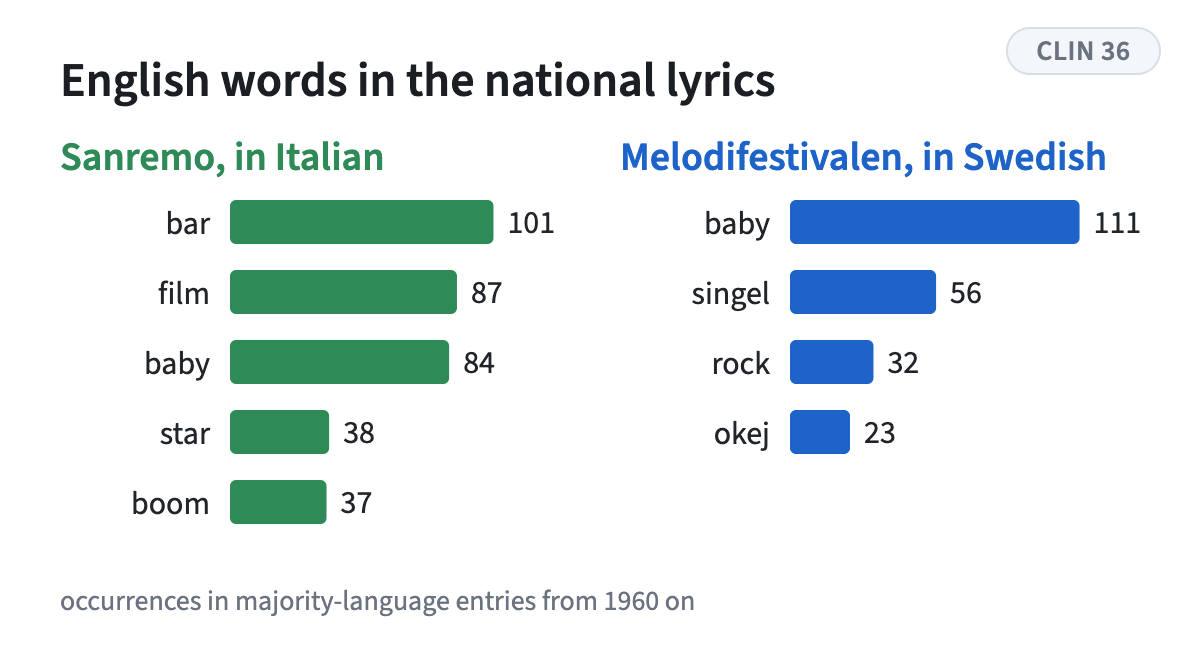
The Sanremo Music Festival and Melodifestivalen are two of Europe’s longest-running song contests. Sanremo has required Italian lyrics throughout its history. Melodifestivalen dropped its Swedish requirement in 2002 and English soon took over. The corpus covers 3,369 entries from 1951 to 2026 with lyrics, metadata, jury and televote results and audio features. From these we derive the language of each song, the English words inside Italian and Swedish lyrics, code-switching within songs, the topics across seven decades, the networks of songwriters, and the emotional arcs of lyrics and music, and we test how each relates to a song’s placement.
The derived data, lexicons and analysis tables are released as the SanreMello Corpus on Hugging Face, with the features dataset, a corpus explorer and the poster. Code: GitHub. Abstract in the CLIN 36 book of abstracts, poster 30.
Citation
@inproceedings{moerman2026sanremello,
  author = {Moerman, Thomas and Singh, Pranaydeep and Teresa Cignarella,
    Alessandra and Kruijsbergen, Joni},
  title = {SanreMello {Corpus:} {Seven} {Decades} of {Sanremo} and
    {Melodifestivalen} in {Data}},
  booktitle = {36th Meeting of Computational Linguistics in the
    Netherlands (CLIN 36), Book of Abstracts},
  pages = {100-101},
  date = {2026-09-11},
  url = {https://clin36.ai.vub.ac.be/CLIN36_book_of_abstracts.pdf},
  langid = {en}
}